


Splunk SPLK-4001 Exam Questions (Updated 2024) 100% Real Question Answers
Pass Splunk SPLK-4001 Exam Quickly With Dumpexams
NEW QUESTION # 33
A customer is experiencing an issue where their detector is not sending email notifications but is generating alerts within the Splunk Observability UI. Which of the below is the root cause?
- A. The detector is disabled.
- B. The detector has an incorrect alert rule.
- C. The detector has an incorrect signal,
- D. The detector has a muting rule.
Answer: D
Explanation:
Explanation
The most likely root cause of the issue is D. The detector has a muting rule.
A muting rule is a way to temporarily stop a detector from sending notifications for certain alerts, without disabling the detector or changing its alert conditions. A muting rule can be useful when you want to avoid alert noise during planned maintenance, testing, or other situations where you expect the metrics to deviate from normal1 When a detector has a muting rule, it will still generate alerts within the Splunk Observability UI, but it will not send email notifications or any other types of notifications that you have configured for the detector. You can see if a detector has a muting rule by looking at the Muting Rules tab on the detector page. You can also create, edit, or delete muting rules from there1 To learn more about how to use muting rules in Splunk Observability Cloud, you can refer to this documentation1.
NEW QUESTION # 34
A user wants to add a link to an existing dashboard from an alert. When they click the dimension value in the alert message, they are taken to the dashboard keeping the context. How can this be accomplished? (select all that apply)
- A. Add a link to the Runbook URL.
- B. Build a global data link.
- C. Add the link to the alert message body.
- D. Add a link to the field.
Answer: B,D
Explanation:
Explanation
The possible ways to add a link to an existing dashboard from an alert are:
Build a global data link. A global data link is a feature that allows you to create a link from any dimension value in any chart or table to a dashboard of your choice. You can specify the source and target dashboards, the dimension name and value, and the query parameters to pass along. When you click on the dimension value in the alert message, you will be taken to the dashboard with the context preserved1 Add a link to the field. A field link is a feature that allows you to create a link from any field value in any search result or alert message to a dashboard of your choice. You can specify the field name and value, the dashboard name and ID, and the query parameters to pass along. When you click on the field value in the alert message, you will be taken to the dashboard with the context preserved2 Therefore, the correct answer is A and C.
To learn more about how to use global data links and field links in Splunk Observability Cloud, you can refer to these documentations12.
1: https://docs.splunk.com/Observability/gdi/metrics/charts.html#Global-data-links 2:
https://docs.splunk.com/Observability/gdi/metrics/search.html#Field-links
NEW QUESTION # 35
Which analytic function can be used to discover peak page visits for a site over the last day?
- A. Count: (Id)
- B. Lag: (24h)
- C. Maximum: Aggregation (Id)
- D. Maximum: Transformation (24h)
Answer: D
Explanation:
Explanation
According to the Splunk Observability Cloud documentation1, the maximum function is an analytic function that returns the highest value of a metric or a dimension over a specified time interval. The maximum function can be used as a transformation or an aggregation. A transformation applies the function to each metric time series (MTS) individually, while an aggregation applies the function to all MTS and returns a single value. For example, to discover the peak page visits for a site over the last day, you can use the following SignalFlow code:
maximum(24h, counters("page.visits"))
This will return the highest value of the page.visits counter metric for each MTS over the last 24 hours. You can then use a chart to visualize the results and identify the peak page visits for each MTS.
NEW QUESTION # 36
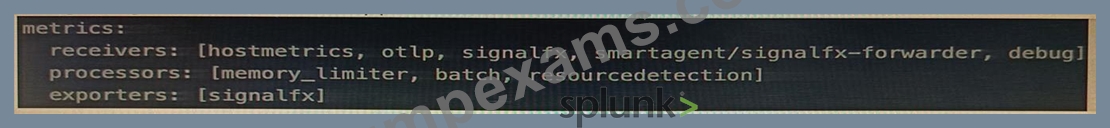
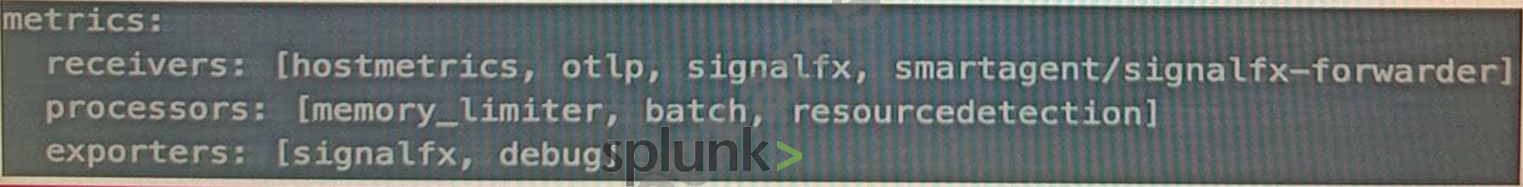
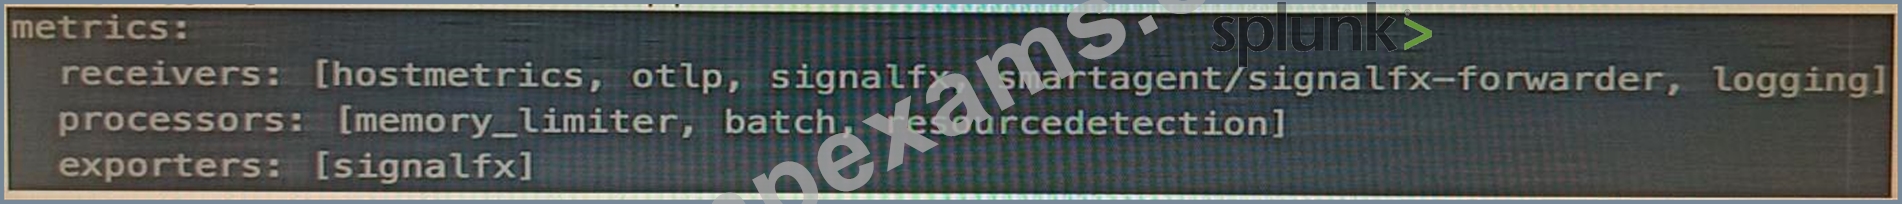
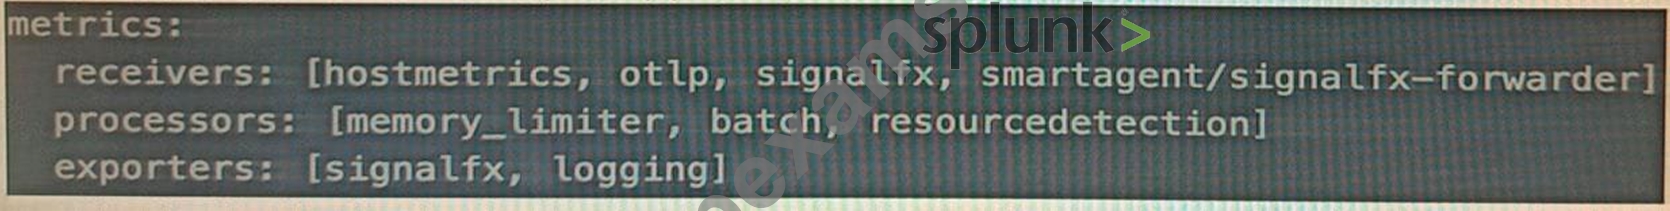
A customer is experiencing issues getting metrics from a new receiver they have configured in the OpenTelemetry Collector. How would the customer go about troubleshooting further with the logging exporter?
- A. Adding debug into the metrics receiver pipeline:
- B. Adding debug into the metrics exporter pipeline:
- C. Adding logging into the metrics receiver pipeline:
- D. Adding logging into the metrics exporter pipeline:
Answer: C
Explanation:
Explanation
The correct answer is B. Adding logging into the metrics receiver pipeline.
The logging exporter is a component that allows the OpenTelemetry Collector to send traces, metrics, and logs directly to the console. It can be used to diagnose and troubleshoot issues with telemetry received and processed by the Collector, or to obtain samples for other purposes1 To activate the logging exporter, you need to add it to the pipeline that you want to diagnose. In this case, since you are experiencing issues with a new receiver for metrics, you need to add the logging exporter to the metrics receiver pipeline. This will create a new plot that shows the metrics received by the Collector and any errors or warnings that might occur1 The image that you have sent with your question shows how to add the logging exporter to the metrics receiver pipeline. You can see that the exporters section of the metrics pipeline includes logging as one of the options.
This means that the metrics received by any of the receivers listed in the receivers section will be sent to the logging exporter as well as to any other exporters listed2 To learn more about how to use the logging exporter in Splunk Observability Cloud, you can refer to this documentation1.
1: https://docs.splunk.com/Observability/gdi/opentelemetry/components/logging-exporter.html 2:
https://docs.splunk.com/Observability/gdi/opentelemetry/exposed-endpoints.html
NEW QUESTION # 37
To smooth a very spiky cpu.utilization metric, what is the correct analytic function to better see if the cpu.
utilization for servers is trending up over time?
- A. Median
- B. Mean (Transformation)
- C. Mean (by host)
- D. Rate/Sec
Answer: B
Explanation:
Explanation
The correct answer is D. Mean (Transformation).
According to the web search results, a mean transformation is an analytic function that returns the average value of a metric or a dimension over a specified time interval1. A mean transformation can be used to smooth a very spiky metric, such as cpu.utilization, by reducing the impact of outliers and noise. A mean transformation can also help to see if the metric is trending up or down over time, by showing the general direction of the average value. For example, to smooth the cpu.utilization metric and see if it is trending up over time, you can use the following SignalFlow code:
mean(1h, counters("cpu.utilization"))
This will return the average value of the cpu.utilization counter metric for each metric time series (MTS) over the last hour. You can then use a chart to visualize the results and compare the mean values across different MTS.
Option A is incorrect because rate/sec is not an analytic function, but rather a rollup function that returns the rate of change of data points in the MTS reporting interval1. Rate/sec can be used to convert cumulative counter metrics into counter metrics, but it does not smooth or trend a metric. Option B is incorrect because median is not an analytic function, but rather an aggregation function that returns the middle value of a metric or a dimension over the entire time range1. Median can be used to find the typical value of a metric, but it does not smooth or trend a metric. Option C is incorrect because mean (by host) is not an analytic function, but rather an aggregation function that returns the average value of a metric or a dimension across all MTS with the same host dimension1. Mean (by host) can be used to compare the performance of different hosts, but it does not smooth or trend a metric.
Mean (Transformation) is an analytic function that allows you to smooth a very spiky metric by applying a moving average over a specified time window. This can help you see the general trend of the metric over time, without being distracted by the short-term fluctuations1 To use Mean (Transformation) on a cpu.utilization metric, you need to select the metric from the Metric Finder, then click on Add Analytics and choose Mean (Transformation) from the list of functions. You can then specify the time window for the moving average, such as 5 minutes, 15 minutes, or 1 hour. You can also group the metric by host or any other dimension to compare the smoothed values across different servers2 To learn more about how to use Mean (Transformation) and other analytic functions in Splunk Observability Cloud, you can refer to this documentation2.
1: https://docs.splunk.com/Observability/gdi/metrics/analytics.html#Mean-Transformation 2:
https://docs.splunk.com/Observability/gdi/metrics/analytics.html
NEW QUESTION # 38
The Sum Aggregation option for analytic functions does which of the following?
- A. Calculates the sum of values present in the input time series across the entire environment or per group.
- B. Calculates 1/2 of the values present in the input time series.
- C. Calculates the number of MTS present in the plot.
- D. Calculates the sum of values per time series across a period of time.
Answer: A
Explanation:
Explanation
According to the Splunk Test Blueprint - O11y Cloud Metrics User document1, one of the metrics concepts that is covered in the exam is analytic functions. Analytic functions are mathematical operations that can be applied to metrics to transform, aggregate, or analyze them.
The Splunk O11y Cloud Certified Metrics User Track document2 states that one of the recommended courses for preparing for the exam is Introduction to Splunk Infrastructure Monitoring, which covers the basics of metrics monitoring and visualization.
In the Introduction to Splunk Infrastructure Monitoring course, there is a section on Analytic Functions, which explains that analytic functions can be used to perform calculations on metrics, such as sum, average, min, max, count, etc. The document also provides examples of how to use analytic functions in charts and dashboards.
One of the analytic functions that can be used is Sum Aggregation, which calculates the sum of values present in the input time series across the entire environment or per group. The document gives an example of how to use Sum Aggregation to calculate the total CPU usage across all hosts in a group by using the following syntax:
sum(cpu.utilization) by hostgroup
NEW QUESTION # 39
A customer is experiencing an issue where their detector is not sending email notifications but is generating alerts within the Splunk Observability UI. Which of the below is the root cause?
- A. The detector is disabled.
- B. The detector has an incorrect alert rule.
- C. The detector has an incorrect signal,
- D. The detector has a muting rule.
Answer: D
Explanation:
Explanation
The most likely root cause of the issue is D. The detector has a muting rule.
A muting rule is a way to temporarily stop a detector from sending notifications for certain alerts, without disabling the detector or changing its alert conditions. A muting rule can be useful when you want to avoid alert noise during planned maintenance, testing, or other situations where you expect the metrics to deviate from normal1 When a detector has a muting rule, it will still generate alerts within the Splunk Observability UI, but it will not send email notifications or any other types of notifications that you have configured for the detector. You can see if a detector has a muting rule by looking at the Muting Rules tab on the detector page. You can also create, edit, or delete muting rules from there1 To learn more about how to use muting rules in Splunk Observability Cloud, you can refer to this documentation1.
NEW QUESTION # 40
What is one reason a user of Splunk Observability Cloud would want to subscribe to an alert?
- A. To receive an email notification when a detector is triggered.
- B. To determine the root cause of the Issue triggering the detector.
- C. To perform transformations on the data used by the detector.
- D. To be able to modify the alert parameters.
Answer: A
Explanation:
Explanation
One reason a user of Splunk Observability Cloud would want to subscribe to an alert is C. To receive an email notification when a detector is triggered.
A detector is a component of Splunk Observability Cloud that monitors metrics or events and triggers alerts when certain conditions are met. A user can create and configure detectors to suit their monitoring needs and goals1 A subscription is a way for a user to receive notifications when a detector triggers an alert. A user can subscribe to a detector by entering their email address in the Subscription tab of the detector page. A user can also unsubscribe from a detector at any time2 When a user subscribes to an alert, they will receive an email notification that contains information about the alert, such as the detector name, the alert status, the alert severity, the alert time, and the alert message. The email notification also includes links to view the detector, acknowledge the alert, or unsubscribe from the detector2 To learn more about how to use detectors and subscriptions in Splunk Observability Cloud, you can refer to these documentations12.
1: https://docs.splunk.com/Observability/alerts-detectors-notifications/detectors.html 2:
https://docs.splunk.com/Observability/alerts-detectors-notifications/subscribe-to-detectors.html
NEW QUESTION # 41
Where does the Splunk distribution of the OpenTelemetry Collector store the configuration files on Linux machines by default?
- A. /etc/otel/collector/
- B. /etc/system/default/
- C. /etc/opentelemetry/
- D. /opt/splunk/
Answer: A
Explanation:
Explanation
The correct answer is B. /etc/otel/collector/
According to the web search results, the Splunk distribution of the OpenTelemetry Collector stores the configuration files on Linux machines in the /etc/otel/collector/ directory by default. You can verify this by looking at the first result1, which explains how to install the Collector for Linux manually. It also provides the locations of the default configuration file, the agent configuration file, and the gateway configuration file.
To learn more about how to install and configure the Splunk distribution of the OpenTelemetry Collector, you can refer to this documentation2.
1: https://docs.splunk.com/Observability/gdi/opentelemetry/install-linux-manual.html 2:
https://docs.splunk.com/Observability/gdi/opentelemetry.html
NEW QUESTION # 42
A customer wants to share a collection of charts with their entire SRE organization. What feature of Splunk Observability Cloud makes this possible?
- A. Dashboard groups
- B. Public dashboards
- C. Chart exporter
- D. Shared charts
Answer: A
Explanation:
Explanation
According to the web search results, dashboard groups are a feature of Splunk Observability Cloud that allows you to organize and share dashboards with other users in your organization1. You can create dashboard groups based on different criteria, such as service, team, role, or topic. You can also set permissions for each dashboard group, such as who can view, edit, or manage the dashboards in the group. Dashboard groups make it possible to share a collection of charts with your entire SRE organization, or any other group of users that you want to collaborate with.
NEW QUESTION # 43
A customer has a very dynamic infrastructure. During every deployment, all existing instances are destroyed, and new ones are created Given this deployment model, how should a detector be created that will not send false notifications of instances being down?
- A. Create the detector. Select Alert settings, then select Auto-Clear Alerts and enter an appropriate time period.
- B. Create the detector. Select Alert settings, then select Ephemeral Infrastructure and enter the expected lifetime of an instance.
- C. Check the Ephemeral checkbox when creating the detector.
- D. Check the Dynamic checkbox when creating the detector.
Answer: B
Explanation:
Explanation
According to the web search results, ephemeral infrastructure is a term that describes instances that are auto-scaled up or down, or are brought up with new code versions and discarded or recycled when the next code version is deployed1. Splunk Observability Cloud has a feature that allows you to create detectors for ephemeral infrastructure without sending false notifications of instances being down2. To use this feature, you need to do the following steps:
Create the detector as usual, by selecting the metric or dimension that you want to monitor and alert on, and choosing the alert condition and severity level.
Select Alert settings, then select Ephemeral Infrastructure. This will enable a special mode for the detector that will automatically clear alerts for instances that are expected to be terminated.
Enter the expected lifetime of an instance in minutes. This is the maximum amount of time that an instance is expected to live before being replaced by a new one. For example, if your instances are replaced every hour, you can enter 60 minutes as the expected lifetime.
Save the detector and activate it.
With this feature, the detector will only trigger alerts when an instance stops reporting a metric unexpectedly, based on its expected lifetime. If an instance stops reporting a metric within its expected lifetime, the detector will assume that it was terminated on purpose and will not trigger an alert. Therefore, option B is correct.
NEW QUESTION # 44
The alert recipients tab specifies where notification messages should be sent when alerts are triggered or cleared. Which of the below options can be used? (select all that apply)
- A. Invoke a webhook URL.
- B. Send to email addresses.
- C. Send an SMS message.
- D. Export to CSV.
Answer: A,B,C
Explanation:
Explanation
The alert recipients tab specifies where notification messages should be sent when alerts are triggered or cleared. The options that can be used are:
Invoke a webhook URL. This option allows you to send a HTTP POST request to a custom URL that can perform various actions based on the alert information. For example, you can use a webhook to create a ticket in a service desk system, post a message to a chat channel, or trigger another workflow1 Send an SMS message. This option allows you to send a text message to one or more phone numbers when an alert is triggered or cleared. You can customize the message content and format using variables and templates2 Send to email addresses. This option allows you to send an email notification to one or more recipients when an alert is triggered or cleared. You can customize the email subject, body, and attachments using variables and templates. You can also include information from search results, the search job, and alert triggering in the email3 Therefore, the correct answer is A, C, and D.
1: https://docs.splunk.com/Documentation/Splunk/latest/Alert/Webhooks 2:
https://docs.splunk.com/Documentation/Splunk/latest/Alert/SMSnotification 3:
https://docs.splunk.com/Documentation/Splunk/latest/Alert/Emailnotification
NEW QUESTION # 45
What constitutes a single metrics time series (MTS)?
- A. A series of timestamps that all reflect the same metric.
- B. A set of metrics that are ordered in series based on timestamp.
- C. A set of data points that use different dimensions but the same metric name.
- D. A set of data points that all have the same metric name and list of dimensions.
Answer: D
Explanation:
Explanation
The correct answer is B. A set of data points that all have the same metric name and list of dimensions.
A metric time series (MTS) is a collection of data points that have the same metric and the same set of dimensions. For example, the following sets of data points are in three separate MTS:
MTS1: Gauge metric cpu.utilization, dimension "hostname": "host1" MTS2: Gauge metric cpu.utilization, dimension "hostname": "host2" MTS3: Gauge metric memory.usage, dimension "hostname": "host1" A metric is a numerical measurement that varies over time, such as CPU utilization or memory usage. A dimension is a key-value pair that provides additional information about the metric, such as the hostname or the location. A data point is a combination of a metric, a dimension, a value, and a timestamp1
NEW QUESTION # 46
The built-in Kubernetes Navigator includes which of the following?
- A. Map, Nodes, Workloads, Node Detail, Workload Detail, Group Detail, Container Detail
- B. Map, Nodes, Workloads, Node Detail, Workload Detail, Pod Detail, Container Detail
- C. Map, Clusters, Workloads, Node Detail, Workload Detail, Pod Detail, Container Detail
- D. Map, Nodes, Processors, Node Detail, Workload Detail, Pod Detail, Container Detail
Answer: B
Explanation:
Explanation
The correct answer is D. Map, Nodes, Workloads, Node Detail, Workload Detail, Pod Detail, Container Detail.
The built-in Kubernetes Navigator is a feature of Splunk Observability Cloud that provides a comprehensive and intuitive way to monitor the performance and health of Kubernetes environments. It includes the following views:
Map: A graphical representation of the Kubernetes cluster topology, showing the relationships and dependencies among nodes, pods, containers, and services. You can use the map to quickly identify and troubleshoot issues in your cluster1 Nodes: A tabular view of all the nodes in your cluster, showing key metrics such as CPU utilization, memory usage, disk usage, and network traffic. You can use the nodes view to compare and analyze the performance of different nodes1 Workloads: A tabular view of all the workloads in your cluster, showing key metrics such as CPU utilization, memory usage, network traffic, and error rate. You can use the workloads view to compare and analyze the performance of different workloads, such as deployments, stateful sets, daemon sets, or jobs1 Node Detail: A detailed view of a specific node in your cluster, showing key metrics and charts for CPU utilization, memory usage, disk usage, network traffic, and pod count. You can also see the list of pods running on the node and their status. You can use the node detail view to drill down into the performance of a single node2 Workload Detail: A detailed view of a specific workload in your cluster, showing key metrics and charts for CPU utilization, memory usage, network traffic, error rate, and pod count. You can also see the list of pods belonging to the workload and their status. You can use the workload detail view to drill down into the performance of a single workload2 Pod Detail: A detailed view of a specific pod in your cluster, showing key metrics and charts for CPU utilization, memory usage, network traffic, error rate, and container count. You can also see the list of containers within the pod and their status. You can use the pod detail view to drill down into the performance of a single pod2 Container Detail: A detailed view of a specific container in your cluster, showing key metrics and charts for CPU utilization, memory usage, network traffic, error rate, and log events. You can use the container detail view to drill down into the performance of a single container2 To learn more about how to use Kubernetes Navigator in Splunk Observability Cloud, you can refer to this documentation3.
1: https://docs.splunk.com/observability/infrastructure/monitor/k8s-nav.html#Kubernetes-Navigator 2:
https://docs.splunk.com/observability/infrastructure/monitor/k8s-nav.html#Detail-pages 3:
https://docs.splunk.com/observability/infrastructure/monitor/k8s-nav.html
NEW QUESTION # 47
Which component of the OpenTelemetry Collector allows for the modification of metadata?
- A. Processors
- B. Exporters
- C. Pipelines
- D. Receivers
Answer: A
Explanation:
Explanation
The component of the OpenTelemetry Collector that allows for the modification of metadata is A. Processors.
Processors are components that can modify the telemetry data before sending it to exporters or other components. Processors can perform various transformations on metrics, traces, and logs, such as filtering, adding, deleting, or updating attributes, labels, or resources. Processors can also enrich the telemetry data with additional metadata from various sources, such as Kubernetes, environment variables, or system information1 For example, one of the processors that can modify metadata is the attributes processor. This processor can update, insert, delete, or replace existing attributes on metrics or traces. Attributes are key-value pairs that provide additional information about the telemetry data, such as the service name, the host name, or the span kind2 Another example is the resource processor. This processor can modify resource attributes on metrics or traces.
Resource attributes are key-value pairs that describe the entity that produced the telemetry data, such as the cloud provider, the region, or the instance type3 To learn more about how to use processors in the OpenTelemetry Collector, you can refer to this documentation1.
1: https://opentelemetry.io/docs/collector/configuration/#processors 2:
https://github.com/open-telemetry/opentelemetry-collector-contrib/tree/main/processor/attributesprocessor 3:
https://github.com/open-telemetry/opentelemetry-collector-contrib/tree/main/processor/resourceprocessor
NEW QUESTION # 48
One server in a customer's data center is regularly restarting due to power supply issues. What type of dashboard could be used to view charts and create detectors for this server?
- A. Machine dashboard
- B. Single-instance dashboard
- C. Multiple-service dashboard
- D. Server dashboard
Answer: B
Explanation:
Explanation
According to the Splunk O11y Cloud Certified Metrics User Track document1, a single-instance dashboard is a type of dashboard that displays charts and information for a single instance of a service or host. You can use a single-instance dashboard to monitor the performance and health of a specific server, such as the one that is restarting due to power supply issues. You can also create detectors for the metrics that are relevant to the server, such as CPU usage, memory usage, disk usage, and uptime. Therefore, option A is correct.
NEW QUESTION # 49
Which of the following aggregate analytic functions will allow a user to see the highest or lowest n values of a metric?
- A. Top / Bottom
- B. Maximum / Minimum
- C. Exclude / Include
- D. Best/Worst
Answer: A
Explanation:
Explanation
The correct answer is D. Top / Bottom.
Top and bottom are aggregate analytic functions that allow a user to see the highest or lowest n values of a metric. They can be used to select a subset of the time series in the plot by count or by percent. For example, top (5) will show the five time series with the highest values in each time period, while bottom (10%) will show the 10% of time series with the lowest values in each time period1 To learn more about how to use top and bottom functions in Splunk Observability Cloud, you can refer to this documentation1.
NEW QUESTION # 50
Which of the following rollups will display the time delta between a datapoint being sent and a datapoint being received?
- A. Jitter
- B. Latency
- C. Lag
- D. Delay
Answer: C
Explanation:
Explanation
According to the Splunk Observability Cloud documentation1, lag is a rollup function that returns the difference between the most recent and the previous data point values seen in the metric time series reporting interval. This can be used to measure the time delta between a data point being sent and a data point being received, as long as the data points have timestamps that reflect their send and receive times. For example, if a data point is sent at 10:00:00 and received at 10:00:05, the lag value for that data point is 5 seconds.
NEW QUESTION # 51
A customer is sending data from a machine that is over-utilized. Because of a lack of system resources, datapoints from this machine are often delayed by up to 10 minutes. Which setting can be modified in a detector to prevent alerts from firing before the datapoints arrive?
- A. Max Delay
- B. Latency
- C. Extrapolation Policy
- D. Duration
Answer: A
Explanation:
Explanation
The correct answer is A. Max Delay.
Max Delay is a parameter that specifies the maximum amount of time that the analytics engine can wait for data to arrive for a specific detector. For example, if Max Delay is set to 10 minutes, the detector will wait for only a maximum of 10 minutes even if some data points have not arrived. By default, Max Delay is set to Auto, allowing the analytics engine to determine the appropriate amount of time to wait for data points1 In this case, since the customer knows that the data from the over-utilized machine can be delayed by up to 10 minutes, they can modify the Max Delay setting for the detector to 10 minutes. This will prevent the detector from firing alerts before the data points arrive, and avoid false positives or missing data1 To learn more about how to use Max Delay in Splunk Observability Cloud, you can refer to this documentation1.
1: https://docs.splunk.com/observability/alerts-detectors-notifications/detector-options.html#Max-Delay
NEW QUESTION # 52
A Software Engineer is troubleshooting an issue with memory utilization in their application. They released a new canary version to production and now want to determine if the average memory usage is lower for requests with the 'canary' version dimension. They've already opened the graph of memory utilization for their service.
How does the engineer see if the new release lowered average memory utilization?
- A. On the chart for plot A, click the Compare Means button. In the window that appears, type 'version1.
- B. On the chart for plot A, select Add Analytics, then select Mean:Aggregation. In the window that appears, select 'version' from the Group By field.
- C. On the chart for plot A, scroll to the end and click Enter Function, then enter 'A/B-l'.
- D. On the chart for plot A, select Add Analytics, then select MeanrTransformation. In the window that appears, select 'version' from the Group By field.
Answer: B
Explanation:
Explanation
The correct answer is C. On the chart for plot A, select Add Analytics, then select Mean:Aggregation. In the window that appears, select 'version' from the Group By field.
This will create a new plot B that shows the average memory utilization for each version of the application.
The engineer can then compare the values of plot B for the 'canary' and 'stable' versions to see if there is a significant difference.
To learn more about how to use analytics functions in Splunk Observability Cloud, you can refer to this documentation1.
1: https://docs.splunk.com/Observability/gdi/metrics/analytics.html
NEW QUESTION # 53
An SRE creates an event feed chart in a dashboard that shows a list of events that meet criteria they specify.
Which of the following should they include? (select all that apply)
- A. Custom events that have been sent in from an external source.
- B. Random alerts from active detectors.
- C. Events created when a detector triggers an alert.
- D. Events created when a detector clears an alert.
Answer: A,C,D
Explanation:
Explanation
According to the web search results1, an event feed chart is a type of chart that shows a list of events that meet criteria you specify. An event feed chart can display one or more event types depending on how you specify the criteria. The event types that you can include in an event feed chart are:
Custom events that have been sent in from an external source: These are events that you have created or received from a third-party service or tool, such as AWS CloudWatch, GitHub, Jenkins, or PagerDuty.
You can send custom events to Splunk Observability Cloud using the API or the Event Ingest Service.
Events created when a detector triggers or clears an alert: These are events that are automatically generated by Splunk Observability Cloud when a detector evaluates a metric or dimension and finds that it meets the alert condition or returns to normal. You can create detectors to monitor and alert on various metrics and dimensions using the UI or the API.
Therefore, option A, B, and D are correct.
NEW QUESTION # 54
For which types of charts can individual plot visualization be set?
- A. Line, Bar, Column
- B. Line, Area, Column
- C. Histogram, Line, Column
- D. Bar, Area, Column
Answer: B
Explanation:
Explanation
The correct answer is C. Line, Area, Column.
For line, area, and column charts, you can set the individual plot visualization to change the appearance of each plot in the chart. For example, you can change the color, shape, size, or style of the lines, areas, or columns. You can also change the rollup function, data resolution, or y-axis scale for each plot1 To set the individual plot visualization for line, area, and column charts, you need to select the chart from the Metric Finder, then click on Plot Chart Options and choose Individual Plot Visualization from the list of options. You can then customize each plot according to your preferences2 To learn more about how to use individual plot visualization in Splunk Observability Cloud, you can refer to this documentation2.
1: https://docs.splunk.com/Observability/gdi/metrics/charts.html#Individual-plot-visualization 2:
https://docs.splunk.com/Observability/gdi/metrics/charts.html#Set-individual-plot-visualization
NEW QUESTION # 55
......
Splunk SPLK-4001 (Splunk O11y Cloud Certified Metrics User) certification exam is designed for individuals who want to showcase their expertise in using Splunk Cloud to monitor and analyze metrics data. Splunk O11y Cloud Certified Metrics User certification exam validates the skills and knowledge required to use Splunk Cloud to collect, store, and analyze metrics data, as well as create dashboards and alerts to monitor system performance. Passing the SPLK-4001 exam demonstrates that an individual has the knowledge and skills required to effectively use Splunk Cloud to monitor and optimize system performance.
Real Splunk SPLK-4001 Exam Questions [Updated 2024]: https://www.dumpexams.com/SPLK-4001-real-answers.html
Prepare SPLK-4001 Question Answers - SPLK-4001 Exam Dumps: https://drive.google.com/open?id=1YKc5b77jwMJOx4s4rh0gz4x8yxbspjdr