


Get instant access to Professional-Machine-Learning-Engineer Practice Tests 2021 Free Updated Today!
Welcome to download the newest PassLeader Professional-Machine-Learning-Engineer PDF dumps ( 72 Q&As)
NEW QUESTION 41
You are training an LSTM-based model on Al Platform to summarize text using the following job submission script: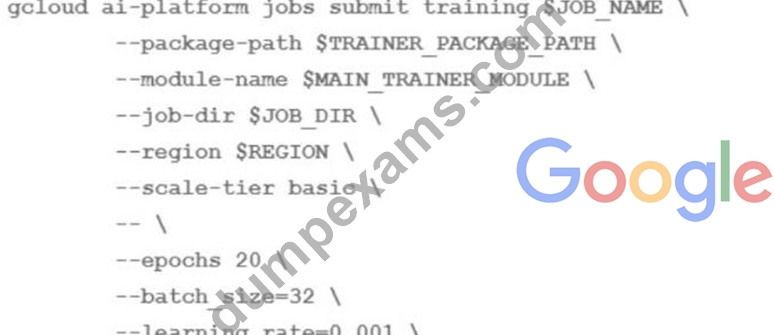
You want to ensure that training time is minimized without significantly compromising the accuracy of your model. What should you do?
- A. Modify the 'scale-tier' parameter
- B. Modify the 'learning rate' parameter
- C. Modify the 'epochs' parameter
- D. Modify the batch size' parameter
Answer: C
NEW QUESTION 42
An agency collects census information within a country to determine healthcare and social program needs by province and city. The census form collects responses for approximately 500 questions from each citizen.
Which combination of algorithms would provide the appropriate insights? (Choose two.)
- A. The factorization machines (FM) algorithm
- B. The k-means algorithm
- C. The Random Cut Forest (RCF) algorithm
- D. The Latent Dirichlet Allocation (LDA) algorithm
- E. The principal component analysis (PCA) algorithm
Answer: B,E
Explanation:
Explanation/Reference:
Explanation:
The PCA and K-means algorithms are useful in collection of data using census form.
NEW QUESTION 43
You are building a model to predict daily temperatures. You split the data randomly and then transformed the training and test datasets. Temperature data for model training is uploaded hourly. During testing, your model performed with 97% accuracy; however, after deploying to production, the model's accuracy dropped to 66%. How can you make your production model more accurate?
- A. Normalize the data for the training, and test datasets as two separate steps.
- B. Apply data transformations before splitting, and cross-validate to make sure that the transformations are applied to both the training and test sets.
- C. Split the training and test data based on time rather than a random split to avoid leakage
- D. Add more data to your test set to ensure that you have a fair distribution and sample for testing
Answer: B
NEW QUESTION 44
You have trained a deep neural network model on Google Cloud. The model has low loss on the training data, but is performing worse on the validation dat a. You want the model to be resilient to overfitting. Which strategy should you use when retraining the model?
- A. Run a hyperparameter tuning job on Al Platform to optimize for the L2 regularization and dropout parameters
- B. Apply a dropout parameter of 0 2, and decrease the learning rate by a factor of 10
- C. Run a hyperparameter tuning job on Al Platform to optimize for the learning rate, and increase the number of neurons by a factor of 2.
- D. Apply a 12 regularization parameter of 0.4, and decrease the learning rate by a factor of 10.
Answer: B
NEW QUESTION 45
You recently designed and built a custom neural network that uses critical dependencies specific to your organization's framework. You need to train the model using a managed training service on Google Cloud. However, the ML framework and related dependencies are not supported by Al Platform Training. Also, both your model and your data are too large to fit in memory on a single machine. Your ML framework of choice uses the scheduler, workers, and servers distribution structure. What should you do?
- A. Build your custom container to run jobs on Al Platform Training
- B. Reconfigure your code to a ML framework with dependencies that are supported by Al Platform Training
- C. Use a built-in model available on Al Platform Training
- D. Build your custom containers to run distributed training jobs on Al Platform Training
Answer: D
NEW QUESTION 46
A Data Scientist is working on an application that performs sentiment analysis. The validation accuracy is poor, and the Data Scientist thinks that the cause may be a rich vocabulary and a low average frequency of words in the dataset.
Which tool should be used to improve the validation accuracy?
- A. Scikit-leam term frequency-inverse document frequency (TF-IDF) vectorizer
- B. Natural Language Toolkit (NLTK) stemming and stop word removal
- C. Amazon Comprehend syntax analysis and entity detection
- D. Amazon SageMaker BlazingText cbowmode
Answer: A
Explanation:
Explanation/Reference: https://monkeylearn.com/sentiment-analysis/
NEW QUESTION 47
You are responsible for building a unified analytics environment across a variety of on-premises data marts. Your company is experiencing data quality and security challenges when integrating data across the servers, caused by the use of a wide range of disconnected tools and temporary solutions. You need a fully managed, cloud-native data integration service that will lower the total cost of work and reduce repetitive work. Some members on your team prefer a codeless interface for building Extract, Transform, Load (ETL) process. Which service should you use?
- A. Dataprep
- B. Apache Flink
- C. Dataflow
- D. Cloud Data Fusion
Answer: D
NEW QUESTION 48
You are an ML engineer at a global car manufacturer. You need to build an ML model to predict car sales in different cities around the world. Which features or feature crosses should you use to train city-specific relationships between car type and number of sales?
- A. One feature obtained as an element-wise product between binned latitude, binned longitude, and one-hot encoded car type
- B. Three individual features binned latitude, binned longitude, and one-hot encoded car type
- C. One feature obtained as an element-wise product between latitude, longitude, and car type
- D. Two feature crosses as a element-wise product the first between binned latitude and one-hot encoded car type, and the second between binned longitude and one-hot encoded car type
Answer: B
NEW QUESTION 49
A company wants to predict the sale prices of houses based on available historical sales data. The target variable in the company's dataset is the sale price. The features include parameters such as the lot size, living area measurements, non-living area measurements, number of bedrooms, number of bathrooms, year built, and postal code. The company wants to use multi-variable linear regression to predict house sale prices.
Which step should a machine learning specialist take to remove features that are irrelevant for the analysis and reduce the model's complexity?
- A. Build a heatmap showing the correlation of the dataset against itself. Remove features with low mutual correlation scores.
- B. Run a correlation check of all features against the target variable. Remove features with low target variable correlation scores.
- C. Plot a histogram of the features and compute their standard deviation. Remove features with low variance.
- D. Plot a histogram of the features and compute their standard deviation. Remove features with high variance.
Answer: B
NEW QUESTION 50
You work with a data engineering team that has developed a pipeline to clean your dataset and save it in a Cloud Storage bucket. You have created an ML model and want to use the data to refresh your model as soon as new data is available. As part of your CI/CD workflow, you want to automatically run a Kubeflow Pipelines training job on Google Kubernetes Engine (GKE). How should you architect this workflow?
- A. Use Cloud Scheduler to schedule jobs at a regular interval. For the first step of the job. check the timestamp of objects in your Cloud Storage bucket If there are no new files since the last run, abort the job.
- B. Configure a Cloud Storage trigger to send a message to a Pub/Sub topic when a new file is available in a storage bucket. Use a Pub/Sub-triggered Cloud Function to start the training job on a GKE cluster
- C. Configure your pipeline with Dataflow, which saves the files in Cloud Storage After the file is saved, start the training job on a GKE cluster
- D. Use App Engine to create a lightweight python client that continuously polls Cloud Storage for new files As soon as a file arrives, initiate the training job
Answer: B
NEW QUESTION 51
When submitting Amazon SageMaker training jobs using one of the built-in algorithms, which common parameters MUST be specified? (Choose three.)
- A. Hyperparameters in a JSON array as documented for the algorithm used.
- B. The training channel identifying the location of training data on an Amazon S3 bucket.
- C. The validation channel identifying the location of validation data on an Amazon S3 bucket.
- D. The output path specifying where on an Amazon S3 bucket the trained model will persist.
- E. The Amazon EC2 instance class specifying whether training will be run using CPU or GPU.
- F. The IAM role that Amazon SageMaker can assume to perform tasks on behalf of the users.
Answer: B,D,E
Explanation:
Explanation
NEW QUESTION 52
You are training a TensorFlow model on a structured data set with 100 billion records stored in several CSV files. You need to improve the input/output execution performance. What should you do?
- A. Load the data into BigQuery and read the data from BigQuery.
- B. Convert the CSV files into shards of TFRecords, and store the data in the Hadoop Distributed File System (HDFS)
- C. Convert the CSV files into shards of TFRecords, and store the data in Cloud Storage
- D. Load the data into Cloud Bigtable, and read the data from Bigtable
Answer: D
NEW QUESTION 53
You work for a large technology company that wants to modernize their contact center. You have been asked to develop a solution to classify incoming calls by product so that requests can be more quickly routed to the correct support team. You have already transcribed the calls using the Speech-to-Text API. You want to minimize data preprocessing and development time. How should you build the model?
- A. Use the Cloud Natural Language API to extract custom entities for classification
- B. Build a custom model to identify the product keywords from the transcribed calls, and then run the keywords through a classification algorithm
- C. Use the Al Platform Training built-in algorithms to create a custom model
- D. Use AutoML Natural Language to extract custom entities for classification
Answer: C
NEW QUESTION 54
A Machine Learning Specialist is building a model that will perform time series forecasting using Amazon SageMaker. The Specialist has finished training the model and is now planning to perform load testing on the endpoint so they can configure Auto Scaling for the model variant.
Which approach will allow the Specialist to review the latency, memory utilization, and CPU utilization during the load test?
- A. Generate an Amazon CloudWatch dashboard to create a single view for the latency, memory utilization, and CPU utilization metrics that are outputted by Amazon SageMaker.
- B. Build custom Amazon CloudWatch Logs and then leverage Amazon ES and Kibana to query and visualize the log data as it is generated by Amazon SageMaker.
- C. Send Amazon CloudWatch Logs that were generated by Amazon SageMaker to Amazon ES and use Kibana to query and visualize the log data.
- D. Review SageMaker logs that have been written to Amazon S3 by leveraging Amazon Athena and Amazon QuickSight to visualize logs as they are being produced.
Answer: A
Explanation:
Explanation/Reference: https://docs.aws.amazon.com/sagemaker/latest/dg/monitoring-cloudwatch.html
NEW QUESTION 55
A retail company is using Amazon Personalize to provide personalized product recommendations for its customers during a marketing campaign. The company sees a significant increase in sales of recommended items to existing customers immediately after deploying a new solution version, but these sales decrease a short time after deployment. Only historical data from before the marketing campaign is available for training.
How should a data scientist adjust the solution?
- A. Use the event tracker in Amazon Personalize to include real-time user interactions.
- B. Add user metadata and use the HRNN-Metadata recipe in Amazon Personalize.
- C. Add event type and event value fields to the interactions dataset in Amazon Personalize.
- D. Implement a new solution using the built-in factorization machines (FM) algorithm in Amazon SageMaker.
Answer: C
NEW QUESTION 56
You work for a large hotel chain and have been asked to assist the marketing team in gathering predictions for a targeted marketing strategy. You need to make predictions about user lifetime value (LTV) over the next 30 days so that marketing can be adjusted accordingly. The customer dataset is in BigQuery, and you are preparing the tabular data for training with AutoML Tables. This data has a time signal that is spread across multiple columns. How should you ensure that AutoML fits the best model to your data?
- A. Manually combine all columns that contain a time signal into an array Allow AutoML to interpret this array appropriately Choose an automatic data split across the training, validation, and testing sets
- B. Submit the data for training without performing any manual transformations Allow AutoML to handle the appropriate transformations Choose an automatic data split across the training, validation, and testing sets
- C. Submit the data for training without performing any manual transformations, and indicate an appropriate column as the Time column Allow AutoML to split your data based on the time signal provided, and reserve the more recent data for the validation and testing sets
- D. Submit the data for training without performing any manual transformations Use the columns that have a time signal to manually split your data Ensure that the data in your validation set is from 30 days after the data in your training set and that the data in your testing set is from 30 days after your validation set
Answer: D
NEW QUESTION 57
You work with a data engineering team that has developed a pipeline to clean your dataset and save it in a Cloud Storage bucket. You have created an ML model and want to use the data to refresh your model as soon as new data is available. As part of your CI/CD workflow, you want to automatically run a Kubeflow Pipelines training job on Google Kubernetes Engine (GKE). How should you architect this workflow?
- A. Use Cloud Scheduler to schedule jobs at a regular interval. For the first step of the job. check the timestamp of objects in your Cloud Storage bucket If there are no new files since the last run, abort the job.
- B. Use App Engine to create a lightweight python client that continuously polls Cloud Storage for new files As soon as a file arrives, initiate the training job
- C. Configure your pipeline with Dataflow, which saves the files in Cloud Storage After the file is saved, start the training job on a GKE cluster
- D. Configure a Cloud Storage trigger to send a message to a Pub/Sub topic when a new file is available in a storage bucket. Use a Pub/Sub-triggered Cloud Function to start the training job on a GKE cluster
Answer: C
NEW QUESTION 58
You have written unit tests for a Kubeflow Pipeline that require custom libraries. You want to automate the execution of unit tests with each new push to your development branch in Cloud Source Repositories. What should you do?
- A. Write a script that sequentially performs the push to your development branch and executes the unit tests on Cloud Run
- B. Set up a Cloud Logging sink to a Pub/Sub topic that captures interactions with Cloud Source Repositories. Execute the unit tests using a Cloud Function that is triggered when messages are sent to the Pub/Sub topic
- C. Set up a Cloud Logging sink to a Pub/Sub topic that captures interactions with Cloud Source Repositories Configure a Pub/Sub trigger for Cloud Run, and execute the unit tests on Cloud Run.
- D. Using Cloud Build, set an automated trigger to execute the unit tests when changes are pushed to your development branch.
Answer: D
NEW QUESTION 59
You are designing an ML recommendation model for shoppers on your company's ecommerce website. You will use Recommendations Al to build, test, and deploy your system. How should you develop recommendations that increase revenue while following best practices?
- A. Because it will take time to collect and record product data, use placeholder values for the product catalog to test the viability of the model.
- B. Use the "Other Products You May Like" recommendation type to increase the click-through rate
- C. Import your user events and then your product catalog to make sure you have the highest quality event stream
- D. Use the "Frequently Bought Together' recommendation type to increase the shopping cart size for each order.
Answer: D
Explanation:
Frequently bought together' recommendations aim to up-sell and cross-sell customers by providing product.
NEW QUESTION 60
A Data Scientist needs to create a serverless ingestion and analytics solution for high-velocity, real-time streaming data.
The ingestion process must buffer and convert incoming records from JSON to a query-optimized, columnar format without data loss. The output datastore must be highly available, and Analysts must be able to run SQL queries against the data and connect to existing business intelligence dashboards.
Which solution should the Data Scientist build to satisfy the requirements?
- A. Create a schema in the AWS Glue Data Catalog of the incoming data format. Use an Amazon Kinesis Data Firehose delivery stream to stream the data and transform the data to Apache Parquet or ORC format using the AWS Glue Data Catalog before delivering to Amazon S3. Have the Analysts query the data directly from Amazon S3 using Amazon Athena, and connect to BI tools using the Athena Java Database Connectivity (JDBC) connector.
- B. Use Amazon Kinesis Data Analytics to ingest the streaming data and perform real-time SQL queries to convert the records to Apache Parquet before delivering to Amazon S3. Have the Analysts query the data directly from Amazon S3 using Amazon Athena and connect to BI tools using the Athena Java Database Connectivity (JDBC) connector.
- C. Write each JSON record to a staging location in Amazon S3. Use the S3 Put event to trigger an AWS Lambda function that transforms the data into Apache Parquet or ORC format and writes the data to a processed data location in Amazon S3. Have the Analysts query the data directly from Amazon S3 using Amazon Athena, and connect to BI tools using the Athena Java Database Connectivity (JDBC) connector.
- D. Write each JSON record to a staging location in Amazon S3. Use the S3 Put event to trigger an AWS Lambda function that transforms the data into Apache Parquet or ORC format and inserts it into an Amazon RDS PostgreSQL database. Have the Analysts query and run dashboards from the RDS database.
Answer: A
Explanation:
Explanation/Reference:
NEW QUESTION 61
......
Oct-2021 Latest Dumpexams Professional-Machine-Learning-Engineer Exam Dumps with PDF and Exam Engine: https://www.dumpexams.com/Professional-Machine-Learning-Engineer-real-answers.html
Premium Quality Google Professional-Machine-Learning-Engineer Online dumps: https://drive.google.com/open?id=1Qjb56M11gIS00CxldHMSFhwJ6-pXK7gu