


Pass Professional-Machine-Learning-Engineer Exam in First Attempt Guaranteed 100% Cover Real Exam Questions [Feb-2023]
Valid Professional-Machine-Learning-Engineer test answers & Google Professional-Machine-Learning-Engineer exam pdf
NEW QUESTION 36
A Machine Learning Specialist is implementing a full Bayesian network on a dataset that describes public transit in New York City. One of the random variables is discrete, and represents the number of minutes New Yorkers wait for a bus given that the buses cycle every 10 minutes, with a mean of 3 minutes.
Which prior probability distribution should the ML Specialist use for this variable?
- A. Uniform distribution
- B. Binomial distribution
- C. Normal distribution
- D. Poisson distribution
Answer: B
NEW QUESTION 37
You work on a data science team at a bank and are creating an ML model to predict loan default risk. You have collected and cleaned hundreds of millions of records worth of training data in a BigQuery table, and you now want to develop and compare multiple models on this data using TensorFlow and Vertex AI. You want to minimize any bottlenecks during the data ingestion state while considering scalability. What should you do?
- A. Convert the data into TFRecords, and use tf.data.TFRecordDataset() to read them.
- B. Use the BigQuery client library to load data into a dataframe, and use tf.data.Dataset.from_tensor_slices() to read it.
- C. Export data to CSV files in Cloud Storage, and use tf.data.TextLineDataset() to read them.
- D. Use TensorFlow I/O's BigQuery Reader to directly read the data.
Answer: C
NEW QUESTION 38
You have a large corpus of written support cases that can be classified into 3 separate categories: Technical Support, Billing Support, or Other Issues. You need to quickly build, test, and deploy a service that will automatically classify future written requests into one of the categories. How should you configure the pipeline?
- A. Use BigQuery ML to build and test a logistic regression model to classify incoming requests. Use BigQuery ML to perform inference.
- B. Use the Cloud Natural Language API to obtain metadata to classify the incoming cases.
- C. Create a TensorFlow model using Google's BERT pre-trained model. Build and test a classifier, and deploy the model using Vertex AI.
- D. Use AutoML Natural Language to build and test a classifier. Deploy the model as a REST API.
Answer: D
Explanation:
AutoML Natural Language is a service that allows you to quickly build, test and deploy natural language processing (NLP) models without needing to have expertise in NLP or machine learning. You can use it to train a classifier on your corpus of written support cases, and then use the AutoML API to perform classification on new requests. Once the model is trained, it can be deployed as a REST API. This allows the classifier to be integrated into your pipeline and be easily consumed by other systems.
NEW QUESTION 39
You are an ML engineer at a large grocery retailer with stores in multiple regions. You have been asked to create an inventory prediction model. Your models features include region, location, historical demand, and seasonal popularity. You want the algorithm to learn from new inventory data on a daily basis. Which algorithms should you use to build the model?
- A. Recurrent Neural Networks (RNN)
- B. Convolutional Neural Networks (CNN)
- C. Classification
- D. Reinforcement Learning
Answer: A
Explanation:
"algorithm to learn from new inventory data on a daily basis" = time series model , best option to deal with time series is forsure RNN
https://builtin.com/data-science/recurrent-neural-networks-and-lstm
NEW QUESTION 40
You work on a growing team of more than 50 data scientists who all use AI Platform. You are designing a strategy to organize your jobs, models, and versions in a clean and scalable way. Which strategy should you choose?
- A. Separate each data scientist's work into a different project to ensure that the jobs, models, and versions created by each data scientist are accessible only to that user.
- B. Set up a BigQuery sink for Cloud Logging logs that is appropriately filtered to capture information about AI Platform resource usage. In BigQuery, create a SQL view that maps users to the resources they are using
- C. Set up restrictive IAM permissions on the AI Platform notebooks so that only a single user or group can access a given instance.
- D. Use labels to organize resources into descriptive categories. Apply a label to each created resource so that users can filter the results by label when viewing or monitoring the resources.
Answer: D
Explanation:
https://cloud.google.com/ai-platform/prediction/docs/resource-labels#overview_of_labels You can add labels to your AI Platform Prediction jobs, models, and model versions, then use those labels to organize resources into categories when viewing or monitoring the resources.
NEW QUESTION 41
Your team is building an application for a global bank that will be used by millions of customers. You built a forecasting model that predicts customers1 account balances 3 days in the future. Your team will use the results in a new feature that will notify users when their account balance is likely to drop below $25. How should you serve your predictions?
- A. 1 Build a notification system on Firebase
2. Register each user with a user ID on the Firebase Cloud Messaging server, which sends a notification when your model predicts that a user's account balance will drop below the $25 threshold - B. 1. Create a Pub/Sub topic for each user
2. Deploy an application on the App Engine standard environment that sends a notification when your model predicts that a user's account balance will drop below the $25 threshold - C. 1. Create a Pub/Sub topic for each user
2 Deploy a Cloud Function that sends a notification when your model predicts that a user's account balance will drop below the $25 threshold. - D. 1. Build a notification system on Firebase
2. Register each user with a user ID on the Firebase Cloud Messaging server, which sends a notification when the average of all account balance predictions drops below the $25 threshold
Answer: B
NEW QUESTION 42
A data scientist wants to use Amazon Forecast to build a forecasting model for inventory demand for a retail company. The company has provided a dataset of historic inventory demand for its products as a .csv file stored in an Amazon S3 bucket. The table below shows a sample of the dataset.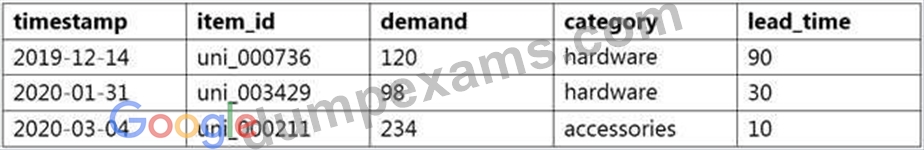
How should the data scientist transform the data?
- A. Use ETL jobs in AWS Glue to separate the dataset into a target time series dataset and an item metadata dataset. Upload both datasets as .csv files to Amazon S3.
- B. Use AWS Batch jobs to separate the dataset into a target time series dataset, a related time series dataset, and an item metadata dataset. Upload them directly to Forecast from a local machine.
- C. Use a Jupyter notebook in Amazon SageMaker to transform the data into the optimized protobuf recordIO format. Upload the dataset in this format to Amazon S3.
- D. Use a Jupyter notebook in Amazon SageMaker to separate the dataset into a related time series dataset and an item metadata dataset. Upload both datasets as tables in Amazon Aurora.
Answer: D
NEW QUESTION 43
You are training a TensorFlow model on a structured data set with 100 billion records stored in several CSV files. You need to improve the input/output execution performance. What should you do?
- A. Load the data into Cloud Bigtable, and read the data from Bigtable
- B. Convert the CSV files into shards of TFRecords, and store the data in the Hadoop Distributed File System (HDFS)
- C. Load the data into BigQuery and read the data from BigQuery.
- D. Convert the CSV files into shards of TFRecords, and store the data in Cloud Storage
Answer: D
NEW QUESTION 44
A gaming company has launched an online game where people can start playing for free, but they need to pay if they choose to use certain features. The company needs to build an automated system to predict whether or not a new user will become a paid user within 1 year. The company has gathered a labeled dataset from 1 million users.
The training dataset consists of 1,000 positive samples (from users who ended up paying within 1 year) and
999,000 negative samples (from users who did not use any paid features). Each data sample consists of 200 features including user age, device, location, and play patterns.
Using this dataset for training, the Data Science team trained a random forest model that converged with over
99% accuracy on the training set. However, the prediction results on a test dataset were not satisfactory Which of the following approaches should the Data Science team take to mitigate this issue? (Choose two.)
- A. Change the cost function so that false negatives have a higher impact on the cost value than false positives.
- B. Change the cost function so that false positives have a higher impact on the cost value than false negatives.
- C. Generate more positive samples by duplicating the positive samples and adding a small amount of noise to the duplicated data.
- D. Include a copy of the samples in the test dataset in the training dataset.
- E. Add more deep trees to the random forest to enable the model to learn more features.
Answer: A,C
NEW QUESTION 45
You work on the data science team at a manufacturing company. You are reviewing the company's historical sales data, which has hundreds of millions of records. For your exploratory data analysis, you need to calculate descriptive statistics such as mean, median, and mode; conduct complex statistical tests for hypothesis testing; and plot variations of the features over time You want to use as much of the sales data as possible in your analyses while minimizing computational resources. What should you do?
- A. Spin up a Vertex Al Workbench user-managed notebooks instance and import the dataset Use this data to create statistical and visual analyses
- B. Use BigQuery to calculate the descriptive statistics. Use Vertex Al Workbench user-managed notebooks to visualize the time plots and run the statistical analyses.
- C. Visualize the time plots in Google Data Studio. Import the dataset into Vertex Al Workbench user-managed notebooks Use this data to calculate the descriptive statistics and run the statistical analyses
Answer: B
Explanation:
D Use BigQuery to calculate the descriptive statistics, and use Google Data Studio to visualize the time plots. Use Vertex Al Workbench user-managed notebooks to run the statistical analyses.
Explanation:
BigQuery is a powerful tool for analyzing large datasets and can be used to quickly calculate descriptive statistics, such as mean, median, and mode, on large amounts of data. By using BigQuery, you can analyze the entire dataset and minimize the computational resources required for your analyses.
Once you have calculated the descriptive statistics, you can use Vertex Al Workbench user-managed notebooks to visualize the time plots and run the statistical analyses. Vertex Al Workbench allows you to interactively explore the data, create visualizations, and perform advanced statistical analysis. It's also possible to run these notebooks on a powerful GPU which will help to increase the speed of the analysis.
NEW QUESTION 46
You are building a model to predict daily temperatures. You split the data randomly and then transformed the training and test datasets. Temperature data for model training is uploaded hourly. During testing, your model performed with 97% accuracy; however, after deploying to production, the model's accuracy dropped to 66%. How can you make your production model more accurate?
- A. Split the training and test data based on time rather than a random split to avoid leakage
- B. Normalize the data for the training, and test datasets as two separate steps.
- C. Apply data transformations before splitting, and cross-validate to make sure that the transformations are applied to both the training and test sets.
- D. Add more data to your test set to ensure that you have a fair distribution and sample for testing
Answer: D
NEW QUESTION 47
A company that promotes healthy sleep patterns by providing cloud-connected devices currently hosts a sleep tracking application on AWS. The application collects device usage information from device users. The company's Data Science team is building a machine learning model to predict if and when a user will stop utilizing the company's devices. Predictions from this model are used by a downstream application that determines the best approach for contacting users.
The Data Science team is building multiple versions of the machine learning model to evaluate each version against the company's business goals. To measure long-term effectiveness, the team wants to run multiple versions of the model in parallel for long periods of time, with the ability to control the portion of inferences served by the models.
Which solution satisfies these requirements with MINIMAL effort?
- A. Build and host multiple models in Amazon SageMaker. Create multiple Amazon SageMaker endpoints, one for each model. Programmatically control invoking different models for inference at the application layer.
- B. Build and host multiple models in Amazon SageMaker Neo to take into account different types of medical devices. Programmatically control which model is invoked for inference based on the medical device type.
- C. Build and host multiple models in Amazon SageMaker. Create a single endpoint that accesses multiple models. Use Amazon SageMaker batch transform to control invoking the different models through the single endpoint.
- D. Build and host multiple models in Amazon SageMaker. Create an Amazon SageMaker endpoint configuration with multiple production variants. Programmatically control the portion of the inferences served by the multiple models by updating the endpoint configuration.
Answer: C
NEW QUESTION 48
Your data science team needs to rapidly experiment with various features, model architectures, and hyperparameters. They need to track the accuracy metrics for various experiments and use an API to query the metrics over time. What should they use to track and report their experiments while minimizing manual effort?
- A. Use Al Platform Training to execute the experiments Write the accuracy metrics to BigQuery, and query the results using the BigQueryAPI.
- B. Use Al Platform Notebooks to execute the experiments. Collect the results in a shared Google Sheets file, and query the results using the Google Sheets API
- C. Use Kubeflow Pipelines to execute the experiments Export the metrics file, and query the results using the Kubeflow Pipelines API.
- D. Use Al Platform Training to execute the experiments Write the accuracy metrics to Cloud Monitoring, and query the results using the Monitoring API.
Answer: A
NEW QUESTION 49
You are building a real-time prediction engine that streams files which may contain Personally Identifiable Information (Pll) to Google Cloud. You want to use the Cloud Data Loss Prevention (DLP) API to scan the files. How should you ensure that the Pll is not accessible by unauthorized individuals?
- A. Stream all files to Google CloudT and then write the data to BigQuery Periodically conduct a bulk scan of the table using the DLP API.
- B. Create two buckets of data Sensitive and Non-sensitive Write all data to the Non-sensitive bucket Periodically conduct a bulk scan of that bucket using the DLP API, and move the sensitive data to the Sensitive bucket
- C. Create three buckets of data: Quarantine, Sensitive, and Non-sensitive Write all data to the Quarantine bucket. Periodically conduct a bulk scan of that bucket using the DLP API, and move the data to either the Sensitive or Non-Sensitive bucket
- D. Stream all files to Google Cloud, and write batches of the data to BigQuery While the data is being written to BigQuery conduct a bulk scan of the data using the DLP API.
Answer: A
NEW QUESTION 50
Your team is working on an NLP research project to predict political affiliation of authors based on articles they have written. You have a large training dataset that is structured like this: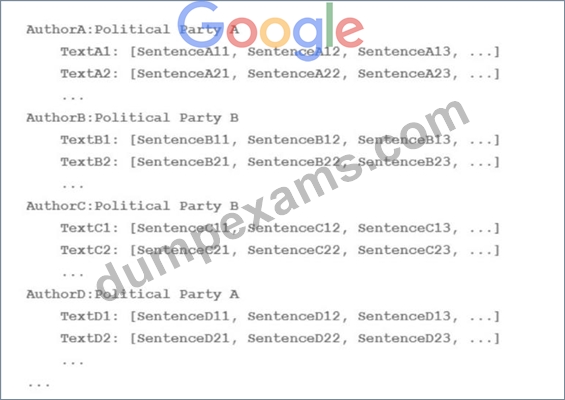
You followed the standard 80%-10%-10% data distribution across the training, testing, and evaluation subsets. How should you distribute the training examples across the train-test-eval subsets while maintaining the 80-10-10 proportion?
A)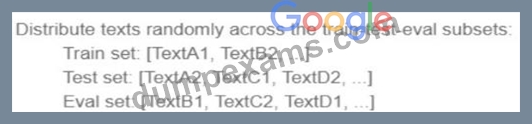
B)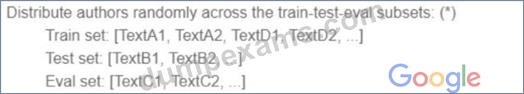
C)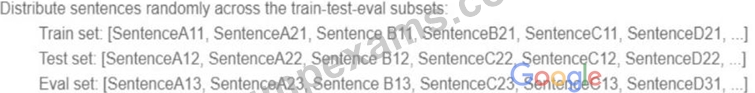
D)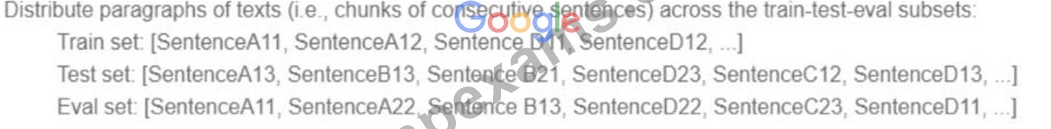
- A. Option A
- B. Option D
- C. Option B
- D. Option C
Answer: C
Explanation:
If we just put inside the Training set , Validation set and Test set , randomly Text, Paragraph or sentences the model will have the ability to learn specific qualities about The Author's use of language beyond just his own articles. Therefore the model will mixed up different opinions. Rather if we divided things up a the author level, so that given authors were only on the training data, or only in the test data or only in the validation data. The model will find more difficult to get a high accuracy on the test validation (What is correct and have more sense!). Because it will need to really focus in author by author articles rather than get a single political affiliation based on a bunch of mixed articles from different authors. https://developers.google.com/machine-learning/crash-course/18th-century-literature For example, suppose you are training a model with purchase data from a number of stores. You know, however, that the model will be used primarily to make predictions for stores that are not in the training data. To ensure that the model can generalize to unseen stores, you should segregate your data sets by stores. In other words, your test set should include only stores different from the evaluation set, and the evaluation set should include only stores different from the training set. https://cloud.google.com/automl-tables/docs/prepare#ml-use
NEW QUESTION 51
......
Professional-Machine-Learning-Engineer Exam Questions – Valid Professional-Machine-Learning-Engineer Dumps Pdf: https://www.dumpexams.com/Professional-Machine-Learning-Engineer-real-answers.html
Verified Professional-Machine-Learning-Engineer dumps Q&As - Pass Guarantee: https://drive.google.com/open?id=1Qjb56M11gIS00CxldHMSFhwJ6-pXK7gu